

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in San Francisco, CA

Fitness • Healthtech • Software
Own reliability and security of CI/CD and production services: define SLI/SLOs, lead incident response and postmortems, build observability (Datadog), operate Kubernetes and IaC (Terraform), harden pipelines with SAST/DAST/SCA and policy-as-code, and coach teams on reliability and operational best practices.
Top Skills:
AWSCi/CdConftestDastDatadogDockerGithub ActionsGoInfrastructure As CodeKubernetesKyvernoOpa/RegoPythonSastScaTerraformTypescript
Artificial Intelligence • Information Technology
Own the reliability, performance, and uptime of large-scale post-training and reinforcement learning systems. Debug distributed failures across accelerators, networking, storage, schedulers, and training frameworks; build monitoring, alerting, recovery, checkpointing, and scheduling tools; improve cluster utilization and fault tolerance; support production model runs through on-call rotations and postmortems; and partner closely with research teams during active training runs.
Top Skills:
C++DpoGoGpuInfinibandKubernetesLinuxNcclPpoPythonPyTorchRayRdmaRlhfSlurmTpu
Artificial Intelligence • Information Technology
Owns end-to-end reliability for Tinker, including CI/CD, observability, service-level objectives, incident response, multi-tenant isolation, resource scheduling, and vulnerability remediation. The role designs monitoring for distributed training systems, improves recovery and checkpointing, and operates Kubernetes clusters supporting heterogeneous GPU workloads. It collaborates closely with platform, security, engineering, and research teams to improve production resilience and utilization.
Top Skills:
Ci/CdCloud InfrastructureDistributed SystemsGpu WorkloadsKubernetesLoraProduction Observability
Cloud • Security • Software • Cybersecurity
Architect, develop, test, and distribute software, services, and infrastructure supporting Akamai’s cloud hypervisor platforms. Improve observability, automate infrastructure processes, troubleshoot complex distributed-system issues, mentor engineers, and participate in on-call service restoration. The role requires deep Linux, kernel, virtualization, ARM hardware, large-scale infrastructure, DevOps, and configuration-management expertise.
Top Skills:
AnsibleArmDevOpsDistributed SystemsKvm/QemuLinuxLinux KernelNested VirtualizationNvidia GraceObservability InfrastructureSaltstack
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s distributed cloud platform. Develop Bash and Python tooling, establish deployment standards, define SLOs, mentor engineers, and troubleshoot complex network issues. The role requires expertise in large-scale distributed systems, TCP/IP, BGP, Linux networking, configuration management, CI/CD, and open-source networking software, with participation in on-call rotations.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip

Software
Owns reliability, observability, performance, and security for a multi-region SaaS platform. Responsibilities include managing Datadog, implementing APM and tracing, defining SLOs, developing automation, expanding infrastructure as code and CI/CD, automating operational workflows, maintaining security controls, participating in incident response, documenting procedures, and mentoring engineers.
Top Skills:
ApmAzure DevopsAzure Kubernetes ServiceAzure SqlBashBicepCi/CdCosmos DbDatadogDistributed TracingHelmInfrastructure As CodeKey VaultKubernetesKustomizeManaged IdentitiesAzureMicrosoft Entra IdPowershellPythonRedisService BusTerraform

Healthtech • Pharmaceutical • Manufacturing
Support operational deployments and maintenance for Core Speech production systems. Implement and maintain monitoring, alerting, performance reporting, and capacity planning. Participate in on-call rotation for off-hours reliability support. Drive improvements to system performance and architecture, and collaborate on projects while complying with corporate and quality standards.

Blockchain • Software
Build, operate, and scale production Kubernetes infrastructure using GitOps and declarative IaC. Design CI/CD workflows, observability, and secure-by-default systems. Troubleshoot networking/storage, participate in on-call rotations, automate operational workflows, and drive postmortems and reliability improvements.
Top Skills:
ArbitrumArgocdArgocd ApplicationsetsAWSAzureBashCloudwatchCodebuildGCPGithub ActionsGitopsGoGrafanaK9SKubernetesLinuxLokiMimirPrometheusPrysmPythonTerraformYamlZerodev

Information Technology • Security • Software • Cybersecurity
Lead reliability strategy across eight engineering groups by defining SLIs, SLOs, and error budgets; strengthening incident response, alerting, postmortems, change safety, and failure testing; and coaching teams to own reliability. The role remains hands-on through production investigations, tooling, dashboards, and reference implementations. It also leads AI adoption in incident management and observability while partnering with architecture, platform, and product teams to improve distributed-system resilience.
Top Skills:
Ai ToolsAWSDatadogDynamoDBElasticsearchGoInfrastructure As CodeKafkaKubernetesObservability ToolingRedisTypescript

Fintech • Professional Services • Software
Own performance, resilience, observability, and incident response for scalable backend systems across product teams. Mentor engineers on secure, reliable coding practices; implement OpenTelemetry, logging, SLOs, and automated testing; and contribute shared infrastructure solutions. The role requires expertise in Java, Spring Boot, REST APIs, microservices, distributed systems, SQL, Docker, Kubernetes, and Helm, with AWS, CI/CD, infrastructure tooling, and financial services experience preferred.
Top Skills:
AWSClaudeDebeziumDockerGitlab Ci/CdHelmJavaKafkaKubernetesMySQLOpentelemetryPostgresRestful ApisSnowflakeSpring BootSQLTemporalTerraform
Artificial Intelligence • Natural Language Processing • Generative AI
Own production safeguards infrastructure for Claude model launches and safety classifier deployments. Configure and verify safeguards across first-party, AWS Bedrock, and GCP Vertex platforms; lead canary rollouts, post-deployment validation, incident response, and rollback decisions. Build automation, continuous validation, repeatable deployment pipelines, and a provenance registry to reduce operational toil and configuration drift. Participate in on-call rotations and launch readiness processes.
Top Skills:
AWSGCPLlm Inference SystemsMl InfrastructurePythonRustTransformer-Based Models
Blockchain • Fintech • Payments • Financial Services • Cryptocurrency • Web3
Design, build, and operate scalable blockchain infrastructure and Kubernetes platforms. Implement IaC, CI/CD, AI-powered automation, monitoring, incident response, and reliability improvements. Mentor engineers, lead cross-functional initiatives, and support network launches, upgrades, and production troubleshooting in a follow-the-sun on-call rotation.
Top Skills:
Agentic AutomationArcBaseBlue-Green DeploymentCanary ReleasesChaos EngineeringCi/CdCloud-Native ToolingContainerizationControllersDnsEthereumGenerative AiGoHelmInfrastructure As CodeKubernetesLoad BalancersMcp ServersObservability ToolingOperatorsPulumiPythonRbacSolanaSQLTerraformVpc
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free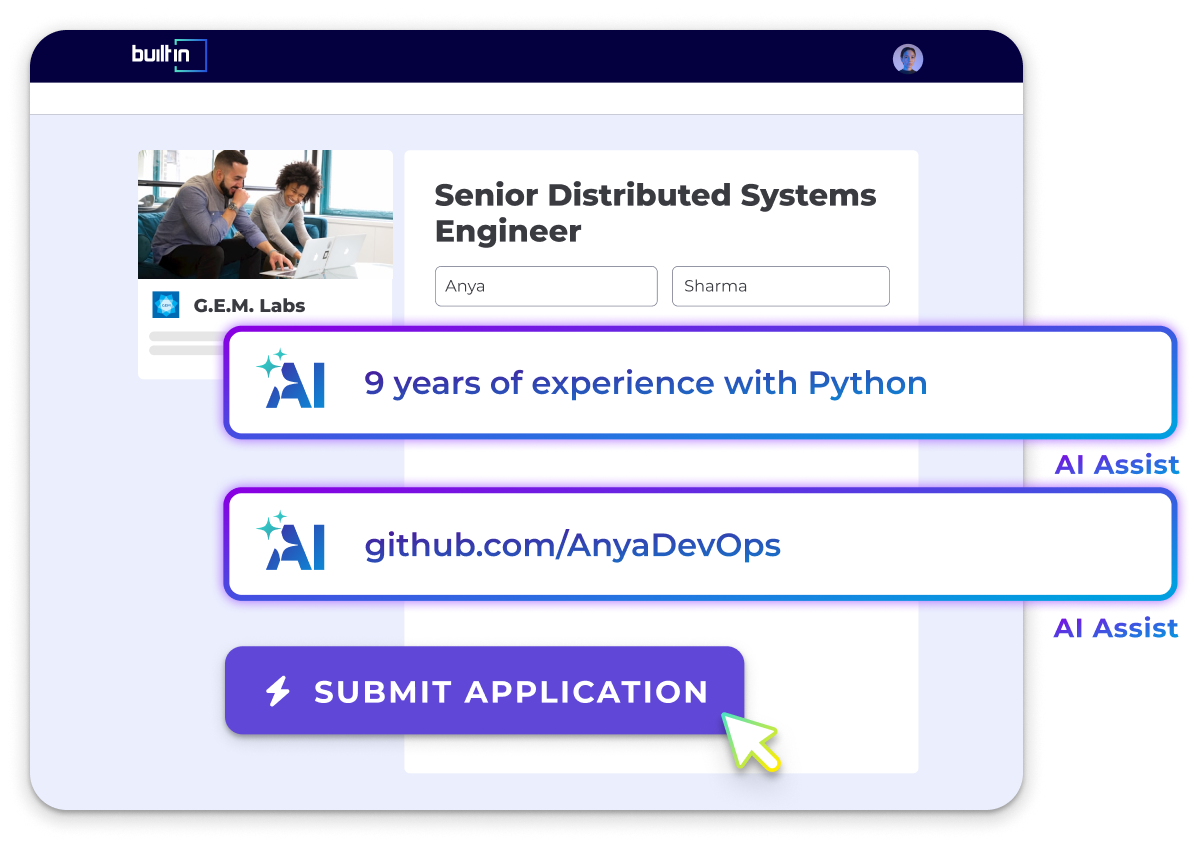

Cloud • Computer Vision • Information Technology • Sales • Security • Cybersecurity
Senior SRE owning availability, automation, and observability for CI/CD platform services. Build and operate infrastructure, run on-call, lead incident response, mentor engineers, drive design/capacity planning, integrate AI-assisted workflows, and improve cross-team reliability.
Top Skills:
Active DirectoryAnsibleApache AirflowSparkAWSAzureBashBazelBitbucketCassandraChefDatadogDnsFirewall RulesGCPGitGithub ActionsGitlabGitlab CiGoGrafanaHoneycombHumio/LogscaleJenkinsKafkaKubernetesLoad BalancersMongoDBMySQLNasNew RelicNfsObject StorageOpensearchOraclePostgresPowershellPrometheusPulsarPuppetPythonRabbitMQRedis/ValkeyRedpandaRoutingSaltSanSplunkTerraformVarnishVipsWindows Server
Cloud • Security • Software • Cybersecurity
Deploys and operates scalable, highly available cloud systems; improves application and network security, stability, speed, and capacity; automates cloud deployments; monitors and troubleshoots services to meet SLAs; analyzes logs and events; manages large-scale cloud infrastructure; and resolves infrastructure issues.
Top Skills:
Amazon Ec2Amazon EventbridgeAmazon Route 53Amazon S3Amazon Web ServicesAnsibleAws LambdaBashCi/CdDockerElastic Load BalancingJenkinsJinjaKubernetesPackerPulumiPython
Insurance
Designs and operates reliable hybrid application platforms, leading CI/CD, infrastructure automation, cloud resource management, monitoring, security scanning, container orchestration, and database self-service tooling. The role owns the enterprise CI/CD technology stack and hosting strategy across on-premises, hybrid, and cloud environments. It requires extensive collaboration with engineering, infrastructure, security, application, QA, and governance teams, along with 24/7 mission-critical support and technical leadership.
Top Skills:
AnsibleApache CamelAWSCi/CdCloudFormationConfluenceDatabase SystemsDockerGitGithub ActionsGitlab CiGradleHelmInfrastructure As CodeJenkinsJIRAKubernetesLinuxMavenMonitoring And AlertingNetworkingPythonSonatypeTerraformVulnerability Scanning

Reposted One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will develop and support distributed storage services, ensuring reliability and operational safety, with a focus on automation and efficiency.
Top Skills:
AWSAzureDnsGoGoogle Cloud PlatformKubernetesLinuxPythonTcp/IpTls

Cloud • Information Technology • Security • Virtual Reality • Cybersecurity
Support reliability, security, scalability, and performance of the TAK CI/CD pipeline and critical infrastructure. Monitor system health, respond to incidents, patch systems, optimize performance and costs, improve DevOps practices, automate operations, and maintain technical documentation. Requires systems and network administration experience, Linux and cloud expertise, containerization, CI/CD knowledge, Zero Trust implementation experience, Security+ certification, and an active T3 investigation.
Top Skills:
AWSCi/Cd PipelinesContainerizationLinuxZero Trust

Automotive
Design and implement scalable cloud infrastructure, monitor performance, automate processes, ensure security and compliance, and lead a DevOps team.
Top Skills:
AWSBashCi/CdDockerElk StackGCPGrafanaKubernetesPrometheusPythonTerraform
Other
Design and operate cloud platforms supporting backend telecom services. Automate deployments, scaling, recovery, and infrastructure provisioning; monitor production systems; maintain observability, alerting, and dashboards; support incident response and on-call operations; manage CI/CD pipelines; and enable engineering, telecom, and data teams through reliable tools and infrastructure.
Top Skills:
AnsibleAWSAzureBashCassandraCircleCICloudFormationDatadogDnsDockerElasticsearchElk StackGitlab CiGoGCPGrafanaHttp/HttpsIamJaegerJenkinsKafkaKubernetesKvmLinuxNoSQLOpentelemetryPerlPrometheusPythonRubySaltstackSplunkSQLTcp/IpTerraformUnixVMware

Artificial Intelligence • HR Tech • Professional Services • Software
Evaluate AI-generated documents, spreadsheets, and presentations for accuracy, rigor, domain quality, and presentation quality in incident management, reliability, and SRE. Apply specialized rubrics, identify factual and aesthetic errors, and provide structured written feedback. This is a fully remote, flexible independent-contractor engagement requiring at least five years of relevant professional experience, English fluency, and proficiency with Microsoft Office and Google Workspace.
Top Skills:
Google SlidesGoogle WorkspaceMS OfficePowerPoint

Big Data • Healthtech • HR Tech • Machine Learning • Software • Telehealth • Big Data Analytics
Own the reliability, performance, resilience, observability, and security of AWS and Kubernetes infrastructure supporting products and AI/ML workloads. Define SLOs, lead incident response and root-cause analysis, build Terraform automation, optimize cloud costs, reduce operational toil, and establish deployment standards that help engineers ship reliably. Participate in on-call rotations and maintain HIPAA-compliant infrastructure.
Top Skills:
AWSClaudeDatadogGitlabGoHipaaIstioKubernetesNatsPostgresPythonSoc 2TerraformTypescript

Fintech • Payments • Financial Services
Leads the design and operation of highly available cloud systems, primarily on AWS, using Terraform, GitLab CI/CD, containers, and observability tools. Responsibilities include reliability engineering, incident response, disaster recovery, automation, monitoring, security integration, vulnerability management, and cost optimization. The role builds internal tools, guides architecture, mentors SRE engineers, documents operational processes, and partners with software engineering teams to improve production reliability and compliance.
Top Skills:
Agentic ApplicationsAmazon Api GatewayAmazon AuroraAmazon CloudfrontAmazon CloudwatchAmazon DynamodbAmazon EbsAmazon Ec2Amazon EcsAmazon EfsAmazon RdsAmazon Route 53Amazon S3Amazon VpcAWSAws FargateAws LambdaAws X-RayDastDatadogDockerGitlabGrafanaIamJavaKubernetesLlmsNew RelicNode.jsOwasp Top 10PythonSastSplunkTerraform
Cloud
Build and manage highly available Kubernetes platforms on AWS. Responsibilities include Kubernetes and Helm platform creation, Terraform infrastructure automation, Karpenter scaling, Istio service mesh management, CI/CD enablement, incident response, security, compliance, monitoring, cost optimization, troubleshooting, and documentation. The role supports multi-region cloud environments and requires federal-environment access eligibility, U.S. Person documentation, and occasional travel for in-person onboarding.
Top Skills:
AnsibleAWSBashCi/CdCircleCICloudFormationCloudwatchDockerEc2EcsEksElk StackGitlabGoGrafanaHelmIamIstioJenkinsKarpenterKubernetesPrometheusPythonRdsS3SpinnakerTerraformVpc

Artificial Intelligence • Software
Design, build, and scale control- and data-plane infrastructure for distributed AI workloads. Improve reliability, performance, scheduling, and observability for Ray clusters across cloud and on-prem environments. Support accelerator integration, container image management, and provide on-call troubleshooting and cross-team collaboration.
Top Skills:
AWSAzureContainersGCPGoGpusGrafanaKubernetesLinuxPrometheusPythonRayTpusVms
Reposted One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Develop and maintain Kubernetes runtime environments, support developers, resolve critical issues, and participate in on-call rotations for production systems.
Top Skills:
AWSAzureCert-ManagerCorednsCrdsCriCsiGatekeeperGCPGoHelmKubernetesKustomizeOperatorsPythonTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top San Francisco Companies Hiring Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
