

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in San Francisco, CA

Cloud • Information Technology • Cybersecurity • Infrastructure as a Service (IaaS)
Owns reliability, observability, and incident response for a GPUaaS platform. Defines SLOs, builds monitoring and alerting systems, leads major incidents and post-incident reviews, automates operational processes, maintains runbooks, manages on-call operations, coordinates with engineering teams, drives chaos testing, reports SLA performance, and mentors junior engineers.
Top Skills:
DatadogGoGpuaasGrafanaGremlinHpcKubernetesLitmusOpentelemetryPrometheusPython
Aerospace • Hardware • Software • Defense • Manufacturing
Build scalable automated solutions for device fleet management, own and optimize MDM platforms, write OS-level scripts for self-healing, gather telemetry to prevent end-user disruption, translate compliance (CMMC) into code-managed baselines, and create dashboards and alerts measuring end-user SLOs.
Top Skills:
AnsibleBashChefFleet DmIntuneJAMFOsqueryPowershellPulumiPuppetPythonSaltTerraformWorkspace One
Cloud
The Senior Site Reliability Engineer will enhance the Splunk ecosystem and develop an Observability Platform by automating infrastructure and managing complex distributed systems, while optimizing log collection and incident response.
Top Skills:
AWSGCPGoKubernetesLinuxOpentelemetryPythonRubySplunkTerraform

Information Technology • Mobile • Software
As a Site Reliability Engineer, you'll ensure system reliability and scalability, automate processes, optimize performance, and collaborate on system design.
Top Skills:
AWSAzureBashCloudFormationDatadogDockerElkGoGoogle Cloud PlatformGrafanaHelmKubernetesNew RelicPrometheusPulumiPythonTerraform

Artificial Intelligence • Software
Own the reliability and performance of backend systems at Gamma, building automation and tooling while leading incident response and improving system stability.
Top Skills:
AWSCloudFormationDockerGoKafkaKubernetesNode.jsPythonTerraformTypescript

Artificial Intelligence • Big Data • Information Technology • Software • Analytics
Own reliability for a live fleet of Linux-based edge sensors and cloud infrastructure. Triage and recover field hardware, perform SSH-based diagnostics, build fleet management and OTA systems, implement observability and alerting, automate operational tasks, develop runbooks, and participate in on-call rotations to prevent and resolve incidents.
Top Skills:
AWSBashCDnsDockerFirewallsGoIamKubernetesLinuxPythonRustSshVpn
Artificial Intelligence • Hardware • Robotics • Software
As a Software Engineer - Infrastructure at Skydio, you'll support and enhance Kubernetes infrastructure, improve continuous delivery, and collaborate on security and architectural improvements.
Top Skills:
Cloud PlatformsContinuous DeploymentGoInfrastructureKubernetesPython
Artificial Intelligence • Cloud • Software • Infrastructure as a Service (IaaS)
Ensure stability and resilience of Runpod's distributed AI platform by defining SLIs/SLOs, leading incident response, building observability and reliability tooling, automating operational workflows, and partnering with engineering teams to reduce toil and improve production readiness.
Top Skills:
BashCi/CdContainerized Production SystemsGoGpu Observability ToolingGrafanaInfrastructure As CodeLinuxPrometheusPython

Edtech
Lead infrastructure modernization and platform reliability across multiple cloud providers. Design infrastructure as code, operate Kubernetes and Linux environments, improve CI/CD and deployment tooling, establish SLI/SLO practices, strengthen observability, lead incident response, manage cloud costs, and partner on security and compliance. Provide technical leadership through architecture guidance, mentorship, engineering standards, and roadmap development while participating in on-call support.
Top Skills:
AWSCi/CdGCPJenkinsKubernetesLinuxPythonRubyRuby On RailsSoc 2SpinnakerTerraform

Cloud • Information Technology • Business Intelligence • Consulting
Design, build, and operate cloud infrastructure and SRE capabilities for an enterprise AI platform. Responsibilities include infrastructure-as-code, landing zones, networking, Kubernetes, CI/CD, observability, incident response, SLOs, production readiness, automation, cost optimization, and support for hybrid, edge, air-gapped, and customer-controlled environments. The role is remote, client-facing, and requires strong collaboration and reliability ownership.
Top Skills:
AlertingAzureAzure ArcAzure DevopsBicepCi/CdDashboardsDockerGithub ActionsGpu WorkloadsInfrastructure As CodeKubernetesLogsMetricsObservabilitySlosTerraformTraces
Blockchain • eCommerce • Fintech • Payments • Software • Financial Services • Cryptocurrency
The Senior Site Reliability Engineer will enhance reliability of Block's platform, improve incident response using AI tools, and coordinate incident management. Responsibilities include building reliable systems, standardizing tools, and leading high-severity incidents during on-call rotations.
Top Skills:
Amazon Web ServicesDatadogDynamoDBGrpcHTTPIstioJavaJSONKotlinKubernetesLaunchdarklyMySQLProtocol BuffersTerraformVitess
Cloud • Security • Software • Cybersecurity
The Site Reliability Engineer II ensures the reliability, availability, performance, and security of critical cloud systems and services. Responsibilities include developing automation for provisioning and configuration management, maintaining monitoring and alerting, optimizing infrastructure performance, supporting high availability, and enabling continuous integration and delivery. The role collaborates with security teams and drives operational improvements across cloud and network infrastructure.
Top Skills:
AnsibleAWSAzureChefContinuous DeliveryContinuous IntegrationDnsElk StackGCPGoGrafanaHTTPKubernetesLinuxPrometheusPuppetPythonShellTcp/IpUnix
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free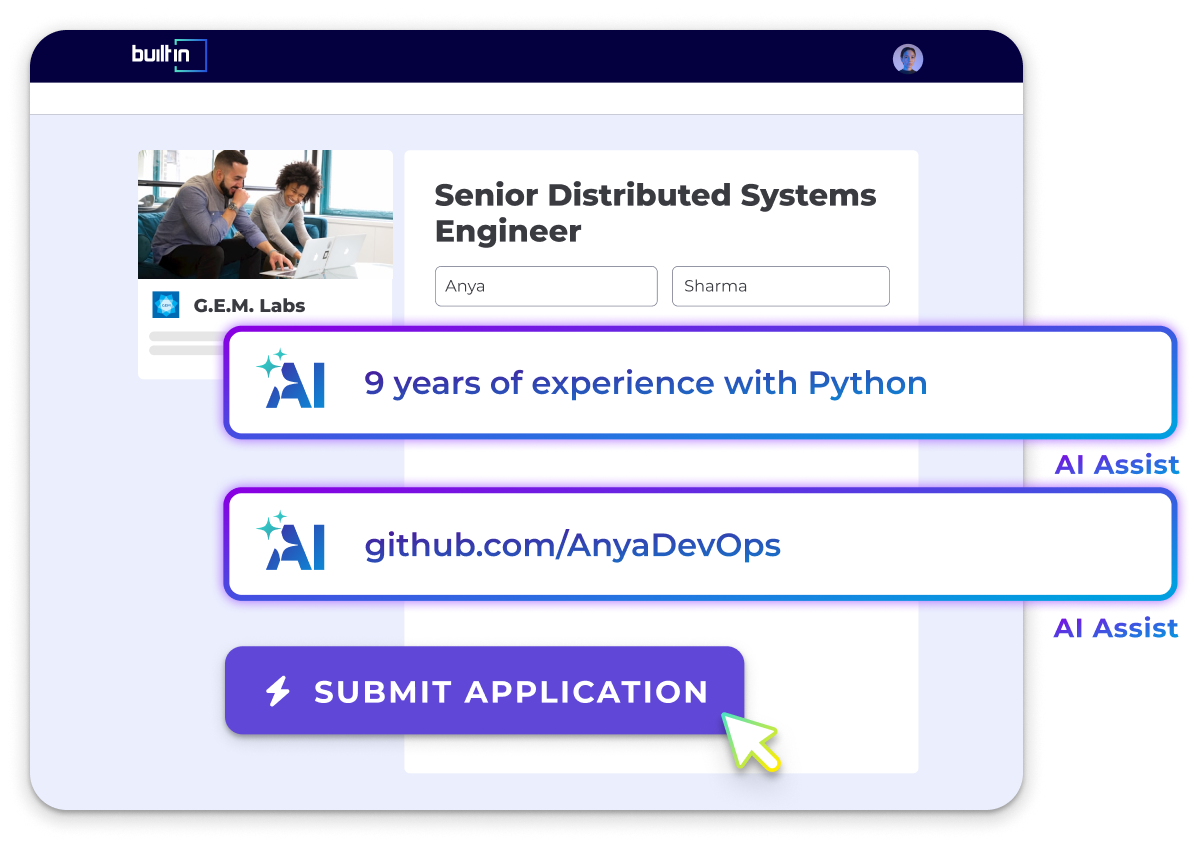

Artificial Intelligence • Information Technology • Software • Automation
Own the reliability, scalability, and observability of production systems. Design and operate AWS infrastructure with Terraform and Kubernetes, build monitoring and SLOs, automate deployments and capacity management, ensure database and data pipeline reliability, partner on architecture reviews, and drive infrastructure security, compliance, and incident response.
Top Skills:
AWSBashCi/CdCloud PlatformsDatadogDistributed SystemsGithub ActionsGrafanaInfrastructure As CodeKubernetesPrometheusPythonTerraform

Fintech • Software • Financial Services
Own AWS and Kubernetes reliability, deployments, observability, incident response, infrastructure as code, CI/CD, and compliance controls for SOC 2 and PCI-DSS. Build scalable platform foundations, AI infrastructure, and greenfield product infrastructure while improving cost efficiency, security, vendor flexibility, and deployment consistency. Participate in on-call support and partner with security and engineering teams across backend, mobile, data, ML, and AI.
Top Skills:
Ai/Llm ToolingAmazon EksAWSAws CdkCi/CdDatadogKotlinKubernetesMcpNode.jsOpentelemetryOpentofuPci-DssPythonSoc 2TerraformTypescript
Cloud • Security • Software • Cybersecurity
Build and maintain reliable, scalable cloud compute platforms across distributed services. Troubleshoot Linux, networking, and production issues; develop automation and AI-assisted tooling; improve monitoring, alerting, SLIs, and SLOs; conduct incident response and root cause analysis; and partner with engineering teams on system design, deployment safety, and operational readiness.
Top Skills:
AnsibleDnsDockerElkGoGrafanaKubernetesLinuxLokiNomadOpensearchPodmanPrometheusPythonSaltTcp/IpTerraform

Artificial Intelligence • Healthtech • Software • Telehealth
Designs, deploys, and maintains resilient AWS and Kubernetes infrastructure. Builds automation, GitHub Actions components, internal AI-assisted operational tools, and observability systems. Leads incident response, postmortems, and SLO/SLI management while ensuring HIPAA compliance and high availability. Collaborates across teams on architecture reviews, risk reduction, clinical safety, and reliability best practices.
Top Skills:
Ai-Assisted OperationsAmazon Ec2Amazon EksAmazon RdsAmazon S3AWSBashDatadogGithub ActionsGoHelmKubernetesPythonTerraform
Artificial Intelligence • Logistics • Software
The Site Reliability Engineer will enhance operational resilience, ensuring system stability, observability, and debugging workflows for complex failures while improving developer focus and uptime.
Top Skills:
DatadogGoPrometheusPythonSentry
Artificial Intelligence • Software
As a Software Engineer on the Site Reliability team, you'll ensure system reliability, scalability, and observability while partnering with engineering teams and improving incident management processes.
Top Skills:
AWSCi/Cd ToolingContainer OrchestrationDatadogGrafanaPrometheusTerraform

Artificial Intelligence • Legal Tech • Professional Services • Software
As a Staff Software Engineer in Site Reliability, you'll manage infrastructure for reliability and scalability, lead incident management, and automate operational tasks.
Top Skills:
AWSAzureBashCloudFormationDatadogGCPGoIncidentioPagerdutyPulumiPythonSentryTerraform
Artificial Intelligence • Legal Tech • Professional Services • Software
As a Software Engineer in Site Reliability, you will ensure the reliability and performance of our AI platform through automation and strategic infrastructure management.
Top Skills:
AWSAzureBashCloudFormationDatadogGCPGoKubernetesPagerdutyPythonSentryTerraform

Information Technology • Software • Big Data Analytics
The Site Reliability Engineer will design, analyze, and troubleshoot large-scale distributed systems, focusing on operating systems and performance tuning.
Top Skills:
ApacheJava

Reposted One Month AgoSaved
Artificial Intelligence • Machine Learning • Robotics • Software • Transportation • Design • Manufacturing
The Staff Site Reliability Engineer will lead source control strategy, manage Git-based monorepo operations, improve developer productivity, and oversee migrations to GitHub Cloud.
Top Skills:
BazelBuckBuildkiteGerritGithub ActionsGithub CloudGithub EnterpriseGitlab CiJenkinsPulumiReviewableTerraform
Artificial Intelligence • Machine Learning • Software • Analytics
The role involves end-to-end ownership of AWS infrastructure, managing Kubernetes platforms, and ensuring system reliability through observability and automation. Responsibilities include incident response and maintaining CI/CD systems.
Top Skills:
ArgocdAWSDatadogGitGoKubernetesPythonTerraform
Reposted One Month AgoSaved
Cloud • Software
Design, deploy, and operate large-scale, multi-region cloud-native services to improve reliability, performance, and security. Partner with application teams to build automation, run SLO-driven incident response and on-call rotations, leverage Kubernetes and CNCF tooling, and implement scalable operations, chaos and scale testing, and infrastructure-as-code for a resilient SaaS platform.
Top Skills:
ArgocdAWSGoKubernetesLinux/UnixOpentelemetryPrometheusPythonService Mesh
Artificial Intelligence • Big Data • Information Technology • Software • Analytics
Own the reliability, scalability, and operational health of an AWS and Kubernetes-based platform supporting connected sensors. Responsibilities include production troubleshooting, incident leadership, infrastructure management with Terraform, automation, CI/CD improvements, observability, service-level objectives, runbooks, and post-incident reviews. The role partners with application, AI, embedded systems, and fleet teams and participates in on-call support.
Top Skills:
Amazon EksAWSBashCCi/CdDnsGitopsGoIamKubernetesLinuxNetworkingPythonRustTerraformVpn

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top San Francisco Companies Hiring Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
