

Maximum of 25 job preferences reached.
Top Remote Data Engineer Jobs in San Francisco Bay Area, CA
Artificial Intelligence • Cloud • Sales • Security • Software • Cybersecurity • Data Privacy
Design, build, and operate scalable batch and streaming data pipelines, lakehouse and warehouse models, and data services. Own datasets end to end, improve Snowflake, Iceberg, Spark, and Flink performance and reliability, implement governance and observability, and support graph-serving data models. Partner with product and engineering teams, participate in on-call, review code and designs, and mentor junior engineers.
Top Skills:
AirflowApache CassandraApache FlinkApache IcebergSparkAWSAzureClaude CodeCloudFormationCursorDatadogDbtGithub CopilotGoogle Cloud PlatformGrafanaJavaKafkaKubernetesMlopsOpensearchPrometheusPythonScalaSnowflakeSQLTerraform

Fintech • Software • Analytics • Financial Services
Design, build, and maintain scalable data pipelines, data lakes, and databases; ingest and map customer financial datasets; monitor pipeline reliability; translate business requirements into data flows and analytical insights to ensure high-quality, usable data.
Top Skills:
APIsBigQueryBigtableData LakesDatabricksDbtFivetranGithub ActionsMariadbMongoDBMySQLNoSQLPostgresRedshiftSnowflakeSQL

Information Technology • Database • Consulting
Lead architecture, development, and optimization of a cloud-native data platform. Design high-volume batch and streaming pipelines, optimize data processing across AWS, Snowflake, Redshift, and Athena, and implement Iceberg-based data management. Establish security, privacy, observability, and DataOps practices while mentoring engineers, guiding technical direction, collaborating with data science teams, and delivering scalable petabyte-level data infrastructure.
Top Skills:
Amazon AthenaAmazon KinesisAmazon RedshiftAmazon S3Apache IcebergAWSAws GlueAws Glue CatalogAws IamAws VpcConfluentDagsterDataopsDbt CoreDevOpsGitPysparkPythonSnowflakeSplunkSQLTalend

Information Technology • Design
Design, build, deploy, and maintain AWS-based data and AI/ML infrastructure for enterprise agentic AI platforms. Develop data lake pipelines, observability systems, agent-enablement tooling, and production MLOps/LLMOps capabilities. Own features end-to-end, contribute to architecture and design decisions, optimize reliability, scalability, security, and cost, and collaborate with AWS Professional Services, client teams, and junior engineers.
Top Skills:
Amazon AthenaAmazon Bedrock AgentsAmazon Bedrock GuardrailsAmazon Bedrock Knowledge BasesAmazon CloudwatchAmazon KinesisAmazon Managed GrafanaAmazon Managed Service For PrometheusAmazon MskAmazon S3Amazon Sagemaker Model MonitorApache IcebergApache ParquetAWSAws CdkAws Distro For OpentelemetryAws GlueAws KmsAws Lake FormationAws X-RayCi/CdClaude CodeCursorIamLanggraphLlmopsMlopsOpentelemetryPythonSQLStrands Agents
Professional Services • Consulting
Build and operate production pipelines for legal records from PACER, court systems, opinions, PDFs, scans, XML, and HTML. Develop LLM-assisted extraction workflows, validate data quality, optimize SQL, and support RAG and semantic search products. Manage AWS S3 and RDS systems within security guardrails while collaborating with engineering teams. The role requires strong Python and SQL skills, legal data experience, document extraction expertise, and autonomous problem-solving with large, messy datasets.
Top Skills:
Amazon RdsAws S3HTMLLarge Language ModelsOcrPdf ParsingPineconePythonRagSemantic SearchSQLVector DatabasesVoyage AiXML
Cloud • Information Technology
Architects, builds, tests, and maintains scalable data infrastructure and ELT/ETL pipelines using AWS Glue, Glue Catalog, and Step Functions. Performs data modeling, SQL querying, data migration, schema optimization, validation, and data quality improvements. Partners with analytics and business teams to transform raw data into production-ready datasets. The role may also support AI/ML pipelines, governance, access controls, DevOps workflows, and real-time data architectures.
Top Skills:
Aws GlueAws Glue CatalogAws Step FunctionsCi/CdData ModelingEltETLMulesoftSQL

Marketing Tech • Consulting
Build and maintain data pipelines for network and operational telemetry, integrate DataMiner and other monitoring systems, create Power BI dashboards, configure monitoring metrics and alerts, automate reporting, analyze network performance and recovery events, and translate technical findings into actionable insights for technical and executive stakeholders.
Top Skills:
Power BISkyline DataminerSQL

Pet • Software
Build and own Snout’s data foundation, including PostgreSQL and dbt warehouses, ingestion pipelines, dimensional models, data quality, documentation, and reliable rebuilds. Reconcile data from veterinary practice-management systems, support LLM/AI tooling, translate stakeholder needs into technical plans, and establish the foundation for a future data team and analyst.
Top Skills:
AWSDbtLlm/AiPostgresPythonSQL

Artificial Intelligence • Machine Learning • Security • Software • Analytics • Big Data Analytics
Design, develop, and operate large-scale data ingestion, transformation, enrichment, and processing pipelines across cloud, hybrid, and on-premises environments. Build distributed services using Java, Python, and Kafka; optimize data models and platform performance; deploy applications on Kubernetes; support infrastructure automation and CI/CD; troubleshoot production systems; and collaborate with customers and solution architects on implementations.
Top Skills:
AWSAzureCi/CdDockerGCPJavaKafkaKubernetesNoSQLPythonSQL

Software
Designs, builds, and operates scalable batch and streaming data pipelines on Databricks for federal missions. Responsibilities include developing Spark and Delta Lake solutions, managing clusters and workflows, implementing Unity Catalog governance and security, optimizing ETL/ELT processes, integrating CI/CD, supporting machine learning and advanced analytics, monitoring data quality, and collaborating with technical teams and stakeholders.
Top Skills:
Amazon EmrSparkAWSAzureCi/CdDatabricksDelta LakeGgplot2GitGCPHadoopHiveKafkaMlflowNoSQLPlotlyPysparkPythonSeabornSpark SqlSpark Structured StreamingSQLUnity Catalog

Healthtech • Information Technology • Mobile • Productivity • Software • Analytics • Telehealth
Design and build maintainable data pipelines, ETL processes, and data architecture standards. Collaborate with product managers, analysts, and machine learning engineers to translate requirements into automated, scalable solutions. Apply software engineering best practices, asynchronous systems, APIs, streaming, testing, monitoring, and Python and SQL expertise. Help prioritize data initiatives based on business impact and communicate complex technical concepts to technical and non-technical stakeholders.
Top Skills:
APIsArtificial IntelligenceETLGitMachine LearningMultithreadingPythonSQLStreaming

Software
Designs and maintains data warehouse infrastructure, semantic and dimensional models, metrics layers, dashboards, reporting, and secure data pipelines. Builds governed self-service analytics in Sigma, Power BI, and Databricks; defines KPIs and data standards; implements row-level security and Entra ID controls; supports data quality, observability, AI/ML use cases, and BI adoption. Collaborates with technical and business stakeholders in an Agile-Scrum environment.
Top Skills:
Agile ScrumAzure DevopsDatabricksDatabricks Ai-Bi GenieDatabricks Asset Bundles (Dab)Databricks Materialized ViewsDatabricks Model ServingDatabricks Vector SearchEntra IdGitGithub CopilotPower BIPythonSigmaSpark SqlSQLT-Sql
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free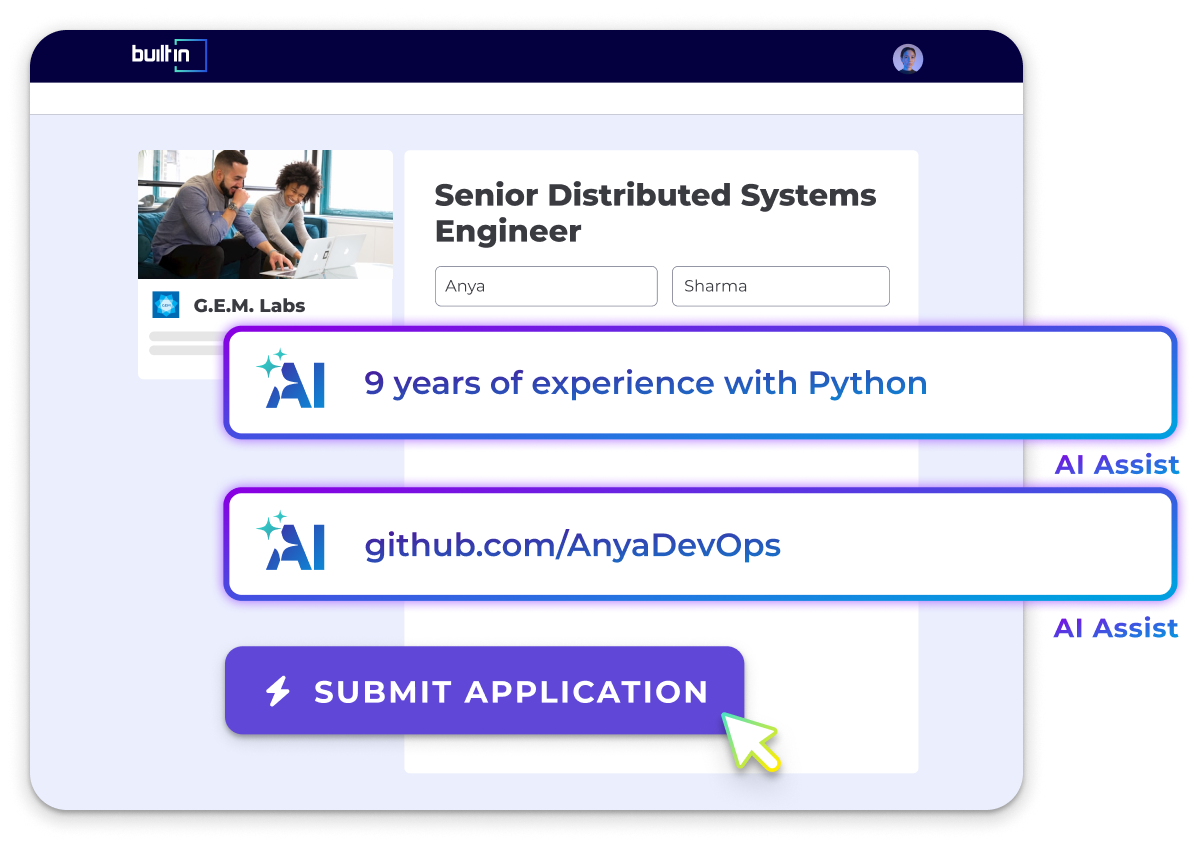

Healthtech
Build and maintain production data ingestion pipelines, transformation models, warehouses, and schemas for PerfectServe’s data platform. Deploy reliable, tested pipelines using idempotency and data-quality checks, apply dimensional and medallion modeling, participate in design reviews, and document owned pipelines and runbooks. The role requires SQL, programming experience, dbt or similar transformation tools, cloud data warehouse experience, ELT orchestration, AWS knowledge, and a strong data-testing mindset.
Top Skills:
Amazon RedshiftApache AirflowAWSBi Semantic LayersBigQueryChange-Data-CaptureDbtDimensional ModelingEltFivetranGoMedallion ArchitecturePythonSnowflakeSQLSQL Server

Information Technology
Design, build, and scale data pipelines, ETL workflows, analytics infrastructure, and machine-learning data systems. Ensure data quality, security, monitoring, and reliability while optimizing storage and processing performance. Collaborate with engineering, product, and analytics teams on data requirements, modeling, schemas, and scalable infrastructure. The role also establishes data engineering best practices and supports a data-driven culture.
Top Skills:
AirflowAWSBigQueryDagsterDockerGCPGoKafkaKinesisKubernetesNode.jsPostgresPrefectPythonRedisRedshiftSnowflakeSQL
Information Technology • Consulting
Lead the design and development of Azure-based big data solutions, including batch and real-time ETL/ELT pipelines, data architecture, ingestion, curation, warehousing, and storage. Build solutions using Azure Data Factory, Databricks, Synapse, Spark, Python, SQL, and related Azure services. Support Salesforce migration and integration while applying strong RDBMS, data management, and big data design expertise.
Top Skills:
AdlsSparkAzure Api ManagementAzure Data FactoryAzure DatabricksAzure Event HubsAzure FunctionsAzure Logic AppsAzure Sql DatabaseAzure SynapseAzure Web AppsDelta LakeInformaticaAzureMicrosoft Sql ServerOracle 10GPythonSalesforceScalaSQLSsis

Fintech • News + Entertainment • Software • Database • Financial Services
Lead the architecture and development of scalable AWS-based data ingestion, transformation, and orchestration pipelines. Build reliable data infrastructure using Python, SQL, Airflow, Lambda, ECS, SQS, and Terraform. Establish data modeling, quality, lineage, monitoring, testing, and observability practices while partnering with analysts, scientists, and backend engineers. Mentor senior engineers, guide technical decisions, and provide hands-on leadership for complex data platform initiatives.
Top Skills:
Amazon EcsAmazon KinesisAmazon RedshiftAmazon S3Amazon SqsApache AirflowApache FlinkAWSAws GlueAws LambdaBeautifulsoupCi/CdDatabricksDockerGreat ExpectationsKafkaMonte CarloMwaaPythonScrapySnowflakeSQLTerraform
Artificial Intelligence • Cloud • Software
Lead the architecture and development of Vercel’s next-generation data platform, supporting batch and real-time integrations, analytics, data warehousing, and AI/ML workloads. Design scalable systems using Kafka, ClickHouse, Tinybird, and Snowflake; establish data governance and security standards; guide architectural decisions and roadmaps; collaborate with engineering, product, security, compliance, and leadership teams; write production code; and mentor engineers.
Top Skills:
AWSAzureBig Data FrameworksClickhouseConfluent PlatformData GovernanceData WarehousingETLGCPKafkaKafka StreamsSnowflakeTinybird

Travel
Build and maintain scalable ETL/ELT pipelines, integrate travel and customer data from internal and external systems, develop cloud data warehouse models, implement data quality monitoring, support real-time streaming, and ensure data privacy and regulatory compliance. Collaborate with analysts, data scientists, and product teams to deliver reliable datasets for personalization, forecasting, pricing, route optimization, and customer experience initiatives.
Top Skills:
AirflowAWSAzureBigQueryCcpaDbtGCPGdprIdmcJavaKafkaPythonRedshiftScalaSnowflakeSQL

Fintech • Information Technology • Other • Payments
Build and maintain Google Cloud data pipelines and ETL/ELT processes supporting GenAI and RAG solutions. Classify and govern sensitive data using Dataplex and Cloud DLP, enforce access controls, assess AI readiness, and design reusable schemas and data models. Collaborate with engineering, delivery, and client teams to integrate legacy systems, monitor pipeline reliability, conduct data quality testing, document data flows, and proactively identify compliance and delivery risks.
Top Skills:
AlationAmazon RedshiftApache AirflowAws MacieAzure SynapseBigQueryC#Cloud ComposerCloud DlpCloud StorageCollibraDataflowDataplexGemini Enterprise Agent PlatformGCPIamJIRANetezzaPostgresPub/SubPythonRagRdbmsSnowflakeSQLSsisTfs

Big Data • Cloud • Productivity • Software • Database • Analytics • Automation
Build and maintain Databricks-based data platforms, including ingestion, transformation, storage, governance, data modeling, and serving pipelines. Establish medallion architecture standards, canonical data models, quality controls, lineage, schema evolution, and reliable batch or incremental processing. Improve pipeline observability, scalability, idempotency, and recoverability while moving curated data to systems such as ClickHouse. Collaborate across application and analytics teams to create durable, governed production datasets.
Top Skills:
Amazon AuroraAmazon RdsApache AirflowSparkBigQueryCdcClickhouseCloud Object StorageDatabricksDelta LakeIamOpenmetadataPostgresSnowflakeUnity Catalog

Machine Learning • Software
Design, build, and operate production data pipelines using Python, Spark SQL, and Airflow. Canonicalize healthcare and customer data into trusted internal models, optimize distributed processing, enforce schemas, and implement quality checks and observability. Support customer onboarding, streaming pipelines, troubleshooting, on-call operations, and platform best practices while collaborating with product, analytics, engineering, data science, and customer teams.
Top Skills:
Amazon SqsApache AirflowAWSCsvJSONKafkaParquetPythonSpark Sql
Machine Learning • Software
Own end-to-end client data migrations: reverse-engineer legacy ETL, design and build Airflow DAGs and Spark jobs, validate and reconcile data at scale, document architecture and decisions, and coordinate cross-functional teams through go-live and hypercare.
Top Skills:
Apache AirflowSparkAws S3ClaudeCursorGithub CopilotPythonSQLSQL ServerSsisT-Sql

Aerospace • Information Technology • Professional Services • Security • Software
Plans and executes enterprise data migrations, conversions, transformations, archival, and cloud data platform operations. Builds ETL/ELT pipelines and migration scripts, performs profiling and source-to-target mapping, validates data, manages cutovers and rollback procedures, and troubleshoots migration issues. Optimizes cloud platforms, databases, workloads, security, access, cost, and performance while collaborating with engineering, governance, architecture, and business teams.
Top Skills:
Amazon RedshiftAWSAws DmsAzure Data FactoryBashCi/CdDatabricksDbtDevsecopsDockerEltETLFedrampGitopsInformaticaJisfKubernetesNistOraclePostgresPythonSnowflakeSQLSQL ServerTalendTerraform

Agency • Information Technology
Develop and optimize enterprise Oracle SQL and PL/SQL solutions, including data models, database designs, APIs, ETL processes, batch jobs, and performance tuning. Collaborate with cross-functional teams to translate requirements into scalable implementations, support testing and CI/CD, troubleshoot production issues, and document solutions. Provide technical leadership, mentor engineers, participate in architecture and code reviews, and drive engineering best practices across data modernization initiatives.
Top Skills:
Acceptance Test Driven DevelopmentAgileAmazon S3Automated TestingAutosysCi/CdCloud Data PlatformsContinuous DeliveryContinuous IntegrationDistributed SystemsETLInformaticaJavaMessaging TechnologiesOracle Pl/SqlOracle SqlScrumSnowflakeTest-Driven DevelopmentWeb/Application Servers
Healthtech
Build and maintain full-stack data engineering solutions supporting BioIntelliSense’s remote patient monitoring and clinical intelligence platform. The role likely involves processing health-monitoring data, enabling analytics, and supporting reporting for clinicians, patients, and employers. Specific responsibilities and qualifications are not provided in the description.

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies in San Francisco Bay Area, CA Hiring Remote Data Engineers
See All






Popular SF Bay Area Remote Job Searches
Remote Jobs in San Francisco Bay Area
Remote .NET Developer Jobs in San Francisco Bay Area
Remote Account Executive (AE) Jobs in San Francisco Bay Area
Remote Account Manager (AM) Jobs in San Francisco Bay Area
Remote Analysis Reporting Jobs in San Francisco Bay Area
Remote Analytics Jobs in San Francisco Bay Area
Remote Android Developer Jobs in San Francisco Bay Area
Remote Business Intelligence Jobs in San Francisco Bay Area
Remote C# Jobs in San Francisco Bay Area
Remote C++ Jobs in San Francisco Bay Area
Remote Content Jobs in San Francisco Bay Area
Remote Customer Success Jobs in San Francisco Bay Area
Remote Cyber Security Jobs in San Francisco Bay Area
Remote Data & Analytics Jobs in San Francisco Bay Area
Remote Data Engineer Jobs in San Francisco Bay Area
Remote Data Management Jobs in San Francisco Bay Area
Remote Data Science Jobs in San Francisco Bay Area
Remote UX Designer Jobs in San Francisco Bay Area
Remote DevOps Jobs in San Francisco Bay Area
Remote Engineering Manager Jobs in San Francisco Bay Area
Remote Finance Jobs in San Francisco Bay Area
Remote Front End Developer Jobs in San Francisco Bay Area
Remote Golang Jobs in San Francisco Bay Area
Remote Hardware Engineer Jobs in San Francisco Bay Area
Remote HR Jobs in San Francisco Bay Area
Remote Internships in San Francisco Bay Area
Remote iOS Developer Jobs in San Francisco Bay Area
Remote IT Jobs in San Francisco Bay Area
Remote Java Developer Jobs in San Francisco Bay Area
Remote Javascript Jobs in San Francisco Bay Area
Remote Legal Jobs in San Francisco Bay Area
Remote Linux Jobs in San Francisco Bay Area
Remote Machine Learning Jobs in San Francisco Bay Area
Remote Marketing Jobs in San Francisco Bay Area
Remote Office Manager Jobs in San Francisco Bay Area
Remote Operations Jobs in San Francisco Bay Area
Remote Operations Manager Jobs in San Francisco Bay Area
Remote PHP Developer Jobs in San Francisco Bay Area
Remote Product Manager Jobs in San Francisco Bay Area
Remote Project Management Jobs in San Francisco Bay Area
Remote Python Jobs in San Francisco Bay Area
Remote QA Engineer Jobs in San Francisco Bay Area
Remote Ruby Jobs in San Francisco Bay Area
Remote Sales Development Representative Jobs in San Francisco Bay Area
Remote Sales Engineer Jobs in San Francisco Bay Area
Remote Sales Jobs in San Francisco Bay Area
Remote Sales Leadership Jobs in San Francisco Bay Area
Remote Sales Operations Jobs in San Francisco Bay Area
Remote Salesforce Developer Jobs in San Francisco Bay Area
Remote Scala Jobs in San Francisco Bay Area
Remote Software Engineer Jobs in San Francisco Bay Area
Remote Tech Support Jobs in San Francisco Bay Area
All Filters
Total selected ()
No Results
No Results
