

Maximum of 25 job preferences reached.
Top Data Engineer Jobs in San Francisco Bay Area, CA

Artificial Intelligence • Productivity • Software
Lead Notion’s Data Foundations team by setting multi-quarter platform strategy, developing engineers and technical leaders, and guiding complex initiatives across data lakes, streaming, distributed compute, governance, and reliability. Drive enterprise-ready capabilities including data residency, access controls, lifecycle management, and key management. Improve Kafka, Debezium, S3/Iceberg, Spark, EMR, and Athena scalability, reliability, usability, and cost efficiency while partnering across engineering, AI, search, infrastructure, and security teams.
Top Skills:
Amazon AthenaAmazon EmrAmazon S3Apache IcebergSparkDebeziumKafka

Healthtech • Telehealth
Build and maintain scalable data pipelines, infrastructure, data models, and APIs using Python, SQL, Airflow, Snowflake, dbt, Terraform, and cloud services. Ensure data quality, security, observability, and reliability while collaborating with analysts, product managers, and engineering teams. Own aspects of the FastAPI data service, including design, deployment, monitoring, and performance. Handle sensitive healthcare data in compliance with governance standards.
Top Skills:
AirflowAWSCi/CdDbtDockerFastapiFlaskGCPKubernetesPostgresPythonRbacSnowflakeSQLTerraform

Big Data • Cloud • Hardware • Software • App development
Lead pre-sales technical engagements to design and optimize scalable cloud lakehouse data platforms (Snowflake/Databricks). Provide architecture reviews, ETL/ELT pipeline design, governance and AI-ready data foundations, support services sales, and translate technical tradeoffs into actionable recommendations for engineering and executive stakeholders.
Top Skills:
Apache AirflowAWSAws RedshiftAws SagemakerAzureAzure AiAzure Data FactoryAzure SynapseCi/CdClaudeCopilotData LineageData ObservabilityDatabricksDatabricks LakeflowDatabricks Mosaic AiDbtDelta LakeDevOpsEvent HubsGleanGoogle BigqueryGCPGoogle Vertex AiInfrastructure As CodeKafkaLakehouse ArchitectureMetadata ManagementNvidia NimPythonSnowflakeSnowflake CortexSnowflake Cortex CodeSnowflake Dynamic TablesSnowflake Streams & TasksSnowparkSQLUnity Catalog

Cloud • Information Technology • Productivity • Security • Software
Lead pre-sales data engineering engagements to design and implement scalable lakehouse data platforms (Snowflake/Databricks). Advise customers on data strategy, governance, pipelines, AI-ready foundations, migrations, and translate technical solutions into business outcomes while supporting sales and partner enablement.
Top Skills:
Apache AirflowAWSAws RedshiftAws SagemakerAzureAzure AiAzure Data FactoryAzure SynapseCi/CdClaudeCopilotData ObservabilityDatabricksDatabricks Mosaic AiDbtDelta LakeDevOpsDynamic TablesEvent HubsGleanGoogle BigqueryGCPGoogle Vertex AiInfrastructure As CodeKafkaLakeflowLakehouseLineage ToolingMetadata ManagementNvidia NimPythonSnowflakeSnowflake CortexSnowflake Cortex CodeSnowparkSQLStreams & TasksUnity Catalog
Artificial Intelligence • Cloud • Sales • Security • Software • Cybersecurity • Data Privacy
Design, build, and operate scalable batch and streaming data pipelines, lakehouse and warehouse models, and data services. Own datasets end to end, improve Snowflake, Iceberg, Spark, and Flink performance and reliability, implement governance and observability, and support graph-serving data models. Partner with product and engineering teams, participate in on-call, review code and designs, and mentor junior engineers.
Top Skills:
AirflowApache CassandraApache FlinkApache IcebergSparkAWSAzureClaude CodeCloudFormationCursorDatadogDbtGithub CopilotGoogle Cloud PlatformGrafanaJavaKafkaKubernetesMlopsOpensearchPrometheusPythonScalaSnowflakeSQLTerraform
Cloud • Healthtech • Social Impact • Software • Biotech
Build and operate production-grade ELT pipelines from Benchling, Salesforce, and third-party systems into Snowflake using dbt. Own ingestion, transformation, warehouse, BI, governance, monitoring, testing, access controls, privacy, cost, and performance. Partner with AI engineering to provide trusted data for internal AI applications and agentic workflows, contribute to warehouse and metrics-layer architecture, and translate cross-functional stakeholder needs into scalable data solutions.
Top Skills:
AirflowAWSDbtPythonSalesforceSnowflakeSQL

Fintech • Software • Analytics • Financial Services
Design, build, and maintain scalable data pipelines, data lakes, and databases; ingest and map customer financial datasets; monitor pipeline reliability; translate business requirements into data flows and analytical insights to ensure high-quality, usable data.
Top Skills:
APIsBigQueryBigtableData LakesDatabricksDbtFivetranGithub ActionsMariadbMongoDBMySQLNoSQLPostgresRedshiftSnowflakeSQL

Artificial Intelligence • Machine Learning • Software • Generative AI
Build and own marketing data, attribution, tracking, audience sync, and conversion infrastructure. Integrate product, CRM, warehouse, and advertising platforms; send offline conversions and LTV signals to ad platforms; maintain event schemas and dashboards; debug data discrepancies; implement privacy-safe tracking; and partner cross-functionally with growth, product, marketing, and data teams.
Top Skills:
AdjustAmplitudeAppsflyerAttBigQueryBranchCmpConsent ModeEltETLGCPGoogle AdsGtmLinkedin AdsMeta AdsMetabasePrivacy SandboxPythonSkanSQLStripeTiktok Ads

Fintech • Software
Own and scale Collective’s data platform by building reliable batch and event-driven pipelines into BigQuery, modeling data with dbt, and enforcing quality, observability, security, and cost standards. Partner with engineers, analysts, and business stakeholders to deliver trustworthy datasets, metrics, reporting, and AI-enabled warehouse access. The role includes production ownership, incident response, governance, infrastructure practices, and support for analytics and LLM-based tools.
Top Skills:
AirflowAmplitudeBigQueryCi/CdClaude CodeCloud ComposerDagsterDatadogDbtFivetranGitGoogle Cloud PlatformInfrastructure As CodeKafkaLlm ToolsMetabaseMetric StoresPub/SubPythonSemantic LayersSQLTerraform

Artificial Intelligence • Big Data • Healthtech • Biotech • Pharmaceutical
Build and operate reliable data systems and products supporting clinical operations, drug evaluation, business development, analytics, machine learning, and AI agents. Responsibilities include designing pipelines, canonical data models, data contracts, warehouse transformations, quality and observability practices, governance for regulated data, and incident response. The role partners closely with Product Engineering and Data Science, uses AI-assisted development, contributes to architecture, and mentors other engineers.
Top Skills:
DagsterDbtDockerGitLlmsOpentofuPythonSnowflakeSQLTerraform
Productivity • Professional Services • Software • Design
Build, test, document, and optimize data pipelines and foundational datasets for Figma’s data warehouse. Interns will support data quality, scalability, analytics, experimentation, and cross-functional data needs while owning a scoped project from definition through implementation, testing, documentation, and results sharing.
Top Skills:
Data PipelinesData WarehousesETLPythonSQL

Information Technology • Database • Consulting
Lead architecture, development, and optimization of a cloud-native data platform. Design high-volume batch and streaming pipelines, optimize data processing across AWS, Snowflake, Redshift, and Athena, and implement Iceberg-based data management. Establish security, privacy, observability, and DataOps practices while mentoring engineers, guiding technical direction, collaborating with data science teams, and delivering scalable petabyte-level data infrastructure.
Top Skills:
Amazon AthenaAmazon KinesisAmazon RedshiftAmazon S3Apache IcebergAWSAws GlueAws Glue CatalogAws IamAws VpcConfluentDagsterDataopsDbt CoreDevOpsGitPysparkPythonSnowflakeSplunkSQLTalend
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free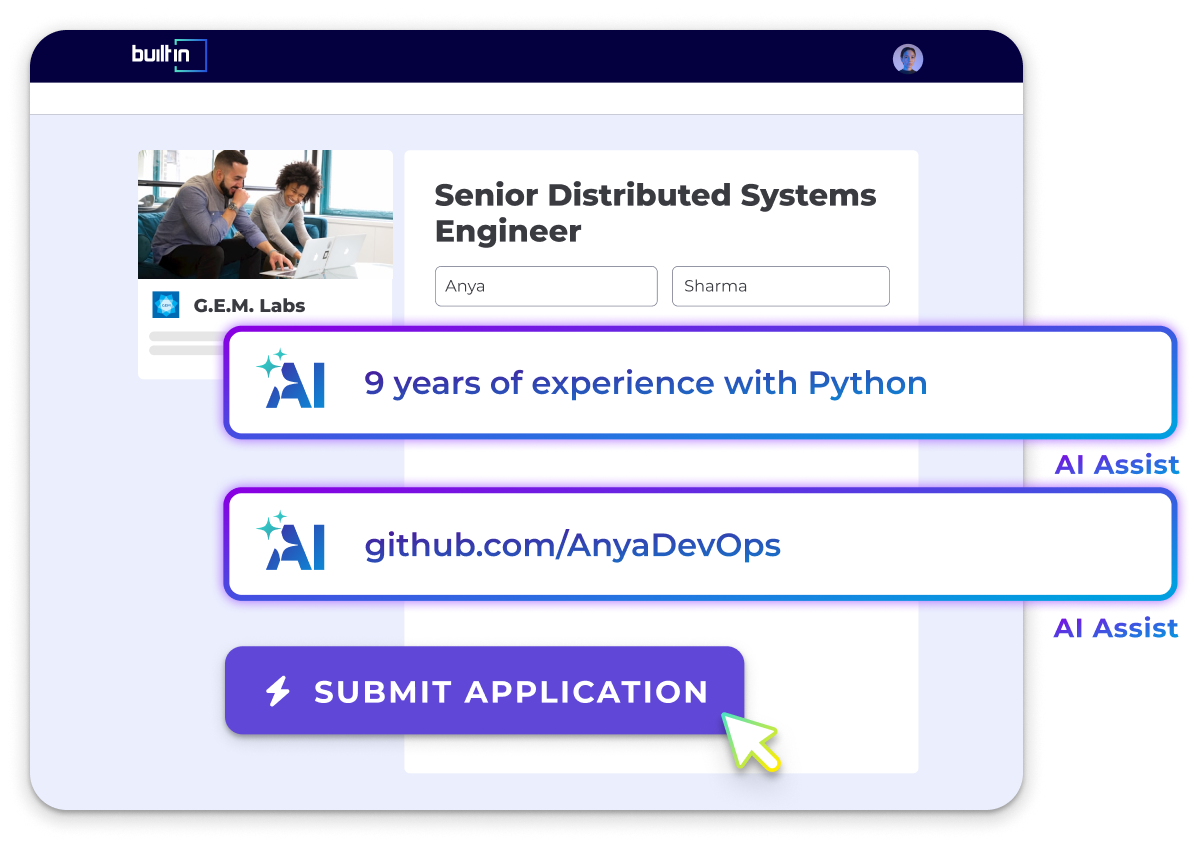
Information Technology • Design
Design, build, deploy, and maintain AWS-based data and AI/ML infrastructure for enterprise agentic AI platforms. Develop data lake pipelines, observability systems, agent-enablement tooling, and production MLOps/LLMOps capabilities. Own features end-to-end, contribute to architecture and design decisions, optimize reliability, scalability, security, and cost, and collaborate with AWS Professional Services, client teams, and junior engineers.
Top Skills:
Amazon AthenaAmazon Bedrock AgentsAmazon Bedrock GuardrailsAmazon Bedrock Knowledge BasesAmazon CloudwatchAmazon KinesisAmazon Managed GrafanaAmazon Managed Service For PrometheusAmazon MskAmazon S3Amazon Sagemaker Model MonitorApache IcebergApache ParquetAWSAws CdkAws Distro For OpentelemetryAws GlueAws KmsAws Lake FormationAws X-RayCi/CdClaude CodeCursorIamLanggraphLlmopsMlopsOpentelemetryPythonSQLStrands Agents
Professional Services • Consulting
Build and operate production pipelines for legal records from PACER, court systems, opinions, PDFs, scans, XML, and HTML. Develop LLM-assisted extraction workflows, validate data quality, optimize SQL, and support RAG and semantic search products. Manage AWS S3 and RDS systems within security guardrails while collaborating with engineering teams. The role requires strong Python and SQL skills, legal data experience, document extraction expertise, and autonomous problem-solving with large, messy datasets.
Top Skills:
Amazon RdsAws S3HTMLLarge Language ModelsOcrPdf ParsingPineconePythonRagSemantic SearchSQLVector DatabasesVoyage AiXML

Machine Learning • Generative AI
Own Modal’s go-to-market data platform, including organization and people graphs, identity resolution, CRM schemas, Snowflake and dbt models, reverse ETL pipelines, revenue operations metrics, forecasting, attribution, and data quality systems. Partner with Data, RevOps, and Marketing to support customer context, routing, territory management, campaigns, reporting, and reliable GTM workflows.
Top Skills:
Ai Coding Tools And AgentsCrm SystemsDbtHexModalPythonReverse EtlSnowflakeSQL
Cloud • Information Technology
Architects, builds, tests, and maintains scalable data infrastructure and ELT/ETL pipelines using AWS Glue, Glue Catalog, and Step Functions. Performs data modeling, SQL querying, data migration, schema optimization, validation, and data quality improvements. Partners with analytics and business teams to transform raw data into production-ready datasets. The role may also support AI/ML pipelines, governance, access controls, DevOps workflows, and real-time data architectures.
Top Skills:
Aws GlueAws Glue CatalogAws Step FunctionsCi/CdData ModelingEltETLMulesoftSQL

Marketing Tech • Consulting
Build and maintain data pipelines for network and operational telemetry, integrate DataMiner and other monitoring systems, create Power BI dashboards, configure monitoring metrics and alerts, automate reporting, analyze network performance and recovery events, and translate technical findings into actionable insights for technical and executive stakeholders.
Top Skills:
Power BISkyline DataminerSQL
Artificial Intelligence • Software • Analytics • Financial Services
Build and operate data pipelines that integrate customer financial data from ERPs, warehouses, and payment systems. Develop AI agents that automate ERP implementations, partner with implementation teams to understand and transform customer data, and contribute to shared AI platform capabilities. The role requires strong full-stack engineering fundamentals, autonomous execution, and comfort working in an ambiguous, fast-moving environment.
Top Skills:
Next.JsPythonReact
Software
Build and scale batch and streaming data pipelines using Databricks, Spark, Kafka, AWS, Python, SQL, dbt, and Fivetran. Develop ETL/ELT and reverse ETL workflows, curated datasets, dashboards, data quality controls, and data activation integrations with Salesforce, HubSpot, and Braze. Partner with Finance, Marketing, Product, and Engineering on reporting, forecasting, segmentation, and AI/ML applications, including RAG, embeddings, and agent-based systems.
Top Skills:
Amazon AthenaAmazon EmrAmazon S3Apache AirflowApache KafkaSparkAWSAws GlueBrazeDatabricksDbtEmbeddingsFivetranHubspotLlmsMcpPysparkPythonRagSalesforceSQLVector Databases

Pet • Software
Build and own Snout’s data foundation, including PostgreSQL and dbt warehouses, ingestion pipelines, dimensional models, data quality, documentation, and reliable rebuilds. Reconcile data from veterinary practice-management systems, support LLM/AI tooling, translate stakeholder needs into technical plans, and establish the foundation for a future data team and analyst.
Top Skills:
AWSDbtLlm/AiPostgresPythonSQL

Artificial Intelligence • Machine Learning • Security • Software • Analytics • Big Data Analytics
Design, develop, and operate large-scale data ingestion, transformation, enrichment, and processing pipelines across cloud, hybrid, and on-premises environments. Build distributed services using Java, Python, and Kafka; optimize data models and platform performance; deploy applications on Kubernetes; support infrastructure automation and CI/CD; troubleshoot production systems; and collaborate with customers and solution architects on implementations.
Top Skills:
AWSAzureCi/CdDockerGCPJavaKafkaKubernetesNoSQLPythonSQL
Healthtech • Information Technology • Mobile • Productivity • Software • Analytics • Telehealth
Design and build maintainable data pipelines, ETL processes, and data architecture standards. Collaborate with product managers, analysts, and machine learning engineers to translate requirements into automated, scalable solutions. Apply software engineering best practices, asynchronous systems, APIs, streaming, testing, monitoring, and Python and SQL expertise. Help prioritize data initiatives based on business impact and communicate complex technical concepts to technical and non-technical stakeholders.
Top Skills:
APIsArtificial IntelligenceETLGitMachine LearningMultithreadingPythonSQLStreaming

Software
Designs, builds, and operates scalable batch and streaming data pipelines on Databricks for federal missions. Responsibilities include developing Spark and Delta Lake solutions, managing clusters and workflows, implementing Unity Catalog governance and security, optimizing ETL/ELT processes, integrating CI/CD, supporting machine learning and advanced analytics, monitoring data quality, and collaborating with technical teams and stakeholders.
Top Skills:
Amazon EmrSparkAWSAzureCi/CdDatabricksDelta LakeGgplot2GitGCPHadoopHiveKafkaMlflowNoSQLPlotlyPysparkPythonSeabornSpark SqlSpark Structured StreamingSQLUnity Catalog
Artificial Intelligence • Machine Learning • Marketing Tech • Social Media • Software
Design, build, and scale reliable data infrastructure, including event ingestion, stream processing, data warehouses, ETL pipelines, analytics tools, and machine learning systems. Optimize performance, reliability, security, and data quality across AWS regions and data centers. Collaborate with analytics and data science teams, troubleshoot complex systems, influence architecture, conduct code reviews, and mentor data engineers while helping establish engineering best practices.
Top Skills:
Apache AirflowApache FlinkApache IcebergSparkAWSBigQueryDagsterData ModelingData WarehousingDatabase DesignDistributed Data ProcessingEltETLGCPMachine Learning InfrastructurePrefectPythonSnowflakeSQLStream Processing
Fintech • Professional Services • Software
Design and build scalable financial data pipelines, data-serving platforms, and AI-enabling frameworks. Ensure data integrity and quality across sources, optimize query performance, troubleshoot data issues, and promote AI-assisted software development. The role requires expertise in Python or Java, databases, warehouses, ETL, batch processing, cloud infrastructure, and Kubernetes, with preferred experience in Snowflake, Airflow, and dbt.
Top Skills:
Apache AirflowSparkAWSClaude CodeCursorData WarehousesDatabase SystemsDbtETLJavaKubernetesPythonSnowflake

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Companies in San Francisco Bay Area, CA Hiring Data Engineers
See All






Popular SF Bay Area Job Searches
Tech Jobs & Startup Jobs in San Francisco Bay Area
Remote Jobs in San Francisco Bay Area
Hybrid Jobs in San Francisco Bay Area
.NET Developer Jobs in San Francisco Bay Area
Account Executive (AE) Jobs in San Francisco Bay Area
Account Manager (AM) Jobs in San Francisco Bay Area
Accounting Jobs in San Francisco Bay Area
Administrative Assistant Jobs in San Francisco Bay Area
AI Engineer Jobs in San Francisco Bay Area
AI Jobs in San Francisco Bay Area
Analysis Reporting Jobs in San Francisco Bay Area
Analytics Jobs in San Francisco Bay Area
Android Developer Jobs in San Francisco Bay Area
Biotech Jobs in San Francisco Bay Area
Business Analyst Jobs in San Francisco Bay Area
Business Intelligence Jobs in San Francisco Bay Area
C# Jobs in San Francisco Bay Area
C++ Jobs in San Francisco Bay Area
Chief of Staff Jobs in San Francisco Bay Area
Communications Jobs in San Francisco Bay Area
Content Jobs in San Francisco Bay Area
Controller Jobs in San Francisco Bay Area
Copywriter Jobs in San Francisco Bay Area
Customer Success Jobs in San Francisco Bay Area
Customer Success Manager Jobs in San Francisco Bay Area
Cyber Security Jobs in San Francisco Bay Area
Data & Analytics Jobs in San Francisco Bay Area
Data Analyst Jobs in San Francisco Bay Area
Data Engineer Jobs in San Francisco Bay Area
Data Management Jobs in San Francisco Bay Area
Data Science Jobs in San Francisco Bay Area
UX Designer Jobs in San Francisco Bay Area
DevOps Engineer Jobs in San Francisco Bay Area
DevOps Jobs in San Francisco Bay Area
Editor Jobs in San Francisco Bay Area
Electrical Engineering Jobs in San Francisco Bay Area
Engineering Jobs in San Francisco Bay Area
Engineering Manager Jobs in San Francisco Bay Area
Executive Assistant Jobs in San Francisco Bay Area
Finance Jobs in San Francisco Bay Area
Finance Manager Jobs in San Francisco Bay Area
Financial Analyst Jobs in San Francisco Bay Area
Front End Developer Jobs in San Francisco Bay Area
Golang Jobs in San Francisco Bay Area
Graphic Design Jobs in San Francisco Bay Area
Hardware Engineer Jobs in San Francisco Bay Area
HR Jobs in San Francisco Bay Area
Human Resources Manager Jobs in San Francisco Bay Area
Internships in San Francisco Bay Area
iOS Developer Jobs in San Francisco Bay Area
IT Jobs in San Francisco Bay Area
Java Developer Jobs in San Francisco Bay Area
Javascript Jobs in San Francisco Bay Area
Legal Jobs in San Francisco Bay Area
Linux Jobs in San Francisco Bay Area
Machine Learning Engineer Jobs in San Francisco Bay Area
Machine Learning Jobs in San Francisco Bay Area
Marketing Jobs in San Francisco Bay Area
Marketing Manager Jobs in San Francisco Bay Area
Mechanical Engineering Jobs in San Francisco Bay Area
Office Manager Jobs in San Francisco Bay Area
Operations Jobs in San Francisco Bay Area
Operations Manager Jobs in San Francisco Bay Area
Paralegal Jobs in San Francisco Bay Area
PHP Developer Jobs in San Francisco Bay Area
Product Designer Jobs in San Francisco Bay Area
Product Manager Jobs in San Francisco Bay Area
Program Manager Jobs in San Francisco Bay Area
Project Management Jobs in San Francisco Bay Area
Python Jobs in San Francisco Bay Area
QA Engineer Jobs in San Francisco Bay Area
QA Jobs in San Francisco Bay Area
Recruiter Jobs in San Francisco Bay Area
Robotics Engineer Jobs in San Francisco Bay Area
Ruby Jobs in San Francisco Bay Area
Sales Development Representative Jobs in San Francisco Bay Area
Sales Engineer Jobs in San Francisco Bay Area
Sales Jobs in San Francisco Bay Area
Sales Leadership Jobs in San Francisco Bay Area
Sales Operations Jobs in San Francisco Bay Area
Sales Representative Jobs in San Francisco Bay Area
Salesforce Developer Jobs in San Francisco Bay Area
Scala Jobs in San Francisco Bay Area
Scientist Jobs in San Francisco Bay Area
Software Engineer Jobs in San Francisco Bay Area
Software Engineering Manager Jobs in San Francisco Bay Area
Staff Accountant Jobs in San Francisco Bay Area
Supply Chain Manager Jobs in San Francisco Bay Area
Tech Support Jobs in San Francisco Bay Area
Technical Program Manager Jobs in San Francisco Bay Area
Writing Jobs in San Francisco Bay Area
All Filters
Total selected ()
No Results
No Results
